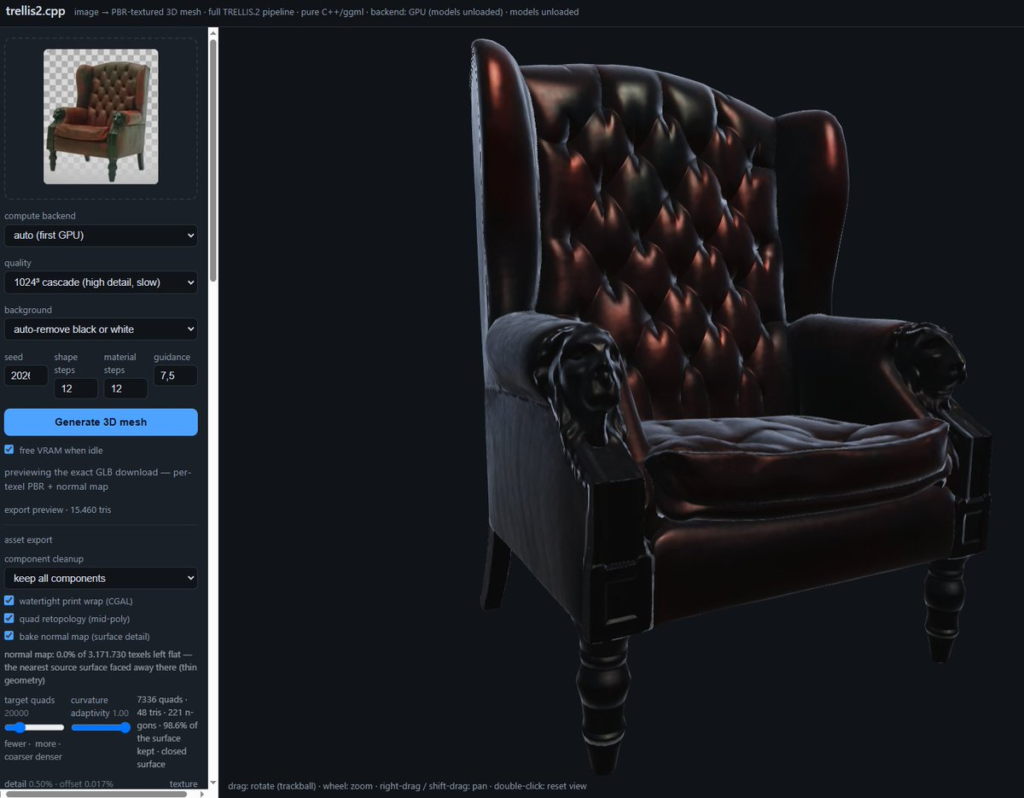
Microsoft’s TRELLIS.2 is excellent and, as shipped, effectively locked to Linux workstations with datacentre GPUs. trellis2.cpp removes that barrier: a C++/GGML port of the full image-to-3D pipeline that is CUDA-free and PyTorch-free.
It is built by the LocalAI team — the same group behind the C++ ports of several other research models — and it powers 3D generation inside LocalAI itself.
Why It Matters
The original requires Linux, CUDA 12.4, a Conda environment and an NVIDIA card with 24 GB of VRAM. The C++ port drops the Python and CUDA stack entirely, loads GGUF weights directly, and runs on far more modest hardware.
LocalAI publishes two profiles:
- Full pipeline — 1024³ cascade with PBR textures, around 18 GB
- Geometry only — 512³ untextured, around 7 GB
Real-world usage sits between those depending on resolution and which components you load — users report full textured generations in the region of 11 GB. The point is that this is now consumer-GPU territory rather than A100 territory.
Graceful Degradation
A genuinely thoughtful design detail: the backend detects which component GGUFs you actually have and adapts. Without the texture models it produces untextured geometry; without the fine-flow models it falls back to a coarse marching-cubes preview.
So you can start with a small download and add components as your hardware allows, rather than facing an all-or-nothing 4B install.
What You Get
- Image to GLB with PBR materials — image-conditioned only, there is no text-prompt path
- Quality tiers — coarse preview, 512 fine dual-grid mesh, or the 1024 high-resolution cascade
- GGUF weights loaded directly — no safetensors conversion, no Python at inference
- A remesh endpoint that outputs watertight, oriented, intersection-free 2-manifold meshes — aimed at 3D printing
- Through LocalAI: a web UI with a native GLB viewer, so you can inspect results in the browser instead of downloading to find out whether they worked
There Is a Second Port Too
Worth knowing: an independent C++/GGML implementation also exists with CUDA and Vulkan backends and a resident HTTP server, with its own pre-built GGUFs. Vulkan matters because it means AMD hardware is in scope — something neither the original nor a CUDA-only port offers.
Honest Expectations
This is a port, not an artist tool. You are running a CLI or a local server, not a Blender add-on. Output is still generated topology — excellent for props and printing, and still requiring a retopology pass before anything gets rigged.
Licensing is inherited MIT from Microsoft’s weights, which is unusually clean for this space.
Developer: LocalAI · Base model: Microsoft TRELLIS.2-4B · Licence: MIT